About

I make models fit where they have to run, then check what they really do.

  • Machine learning engineer
  • India
  • English and Hindi
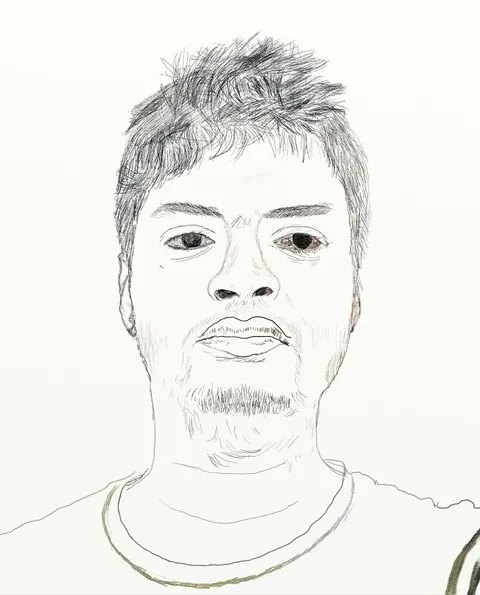
A sketch of Rahul Kumar

What I work on

Large models and fast frameworks

I serve a language model bigger than my GPU's memory from that one GPU. In open-source Keras, I made the PyTorch backend faster and added one call that turns a trained model into a file a phone can run. See GLM-5.3-Flash on one GPU, Keras on PyTorch and LiteRT export.

On-device vision and sensing

These models run on the device itself, with no server to lean on. They read badly damaged barcodes and recognise many faces at once. From touch and motion, they can tell which hand holds a phone, who is using it, and when it is falling. See damaged barcodes, face recognition and drop detection.

Projects of my own

RL Alpha Labs is automated trading on Indian stocks: an idea stays only if it beats an index fund after costs and tax. Porchlamp ranks open-source projects by what happens to a stranger's pull request, not by their stars.

How I work

  • Measure first. I profile before changing anything, change one thing at a time, and time the commit before and after.
  • Report the number that decides. For trading, returns after costs and tax; for speed, the setting that ships, not the best run.
  • One cause per change. Fixes go upstream as small pull requests, each easy to review and easy to revert.
  • Write down what failed. Every closed idea and dead end keeps its reason, so nobody has to find it out twice.

The lamp in the logo stands for that last habit: a light left on for whoever checks next.

Get in touch

LinkedIn is the quickest way to reach me. Email works too.

Also on DEV, Medium, Hashnode and Kaggle.